Understanding Player Strategies and AI Perspectives

Poker is more than a game; it’s an interesting choreography of deductive reasoning, psychology, and decision-making. Every hand has a story behind it, and every decision one makes is an amalgamation of past experience and intuition, spiced up with a tinge of unpredictability. From a classical player’s perspective, poker is strikingly human; it is all about reading your opponent, managing risks, and handling uncertainty.

But then, there is the flip side. Change the lens to AI, and poker acquires a whole new dimension. For an AI engineer, poker is a well-posed problem. This is a game of finite states, probability, and optimization, where seemingly infinite complexity in human behavior goes down to numbers and algorithms.

Let us break this dualism down and examine the philosophy of poker from a human and an AI perspective.

What Is Poker to an AI Engineer?

Poker, in simple terms, is a game, a well-defined set of rules that governs interactions among players. But unlike any other game, poker is intrinsically based on incomplete information. This very inability to know makes poker such fertile ground for human creativity and AI modeling.

Key elements of poker strategy from the artificial intelligence perspective:

  • Finite states: A finite number of variables specify the situation at every point in poker: chips, cards, the amount of possible acts (check, call, raise).
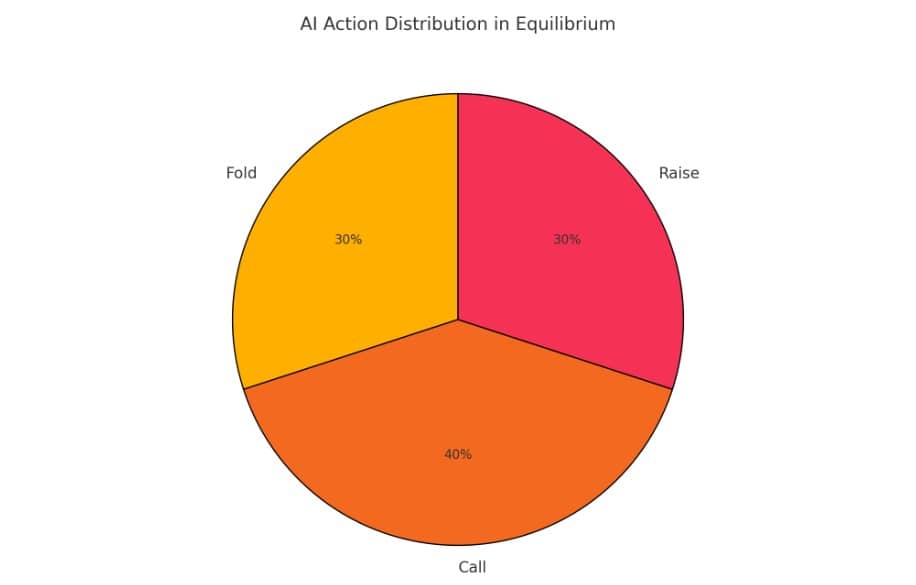
  • Mixed moves: Players are not deterministic. They attach a probability weight to every possible act they may perform, e.g., calling 45% of the time and folding 55% of the time. This injects randomness into the game.
  • Expected profit: Each decision, whether deterministic or randomized, can be evaluated through the concept of a long-run average payoff.

This formalized vision reduces poker to a mathematical problem, an optimization problem whose solution involves probabilities and optimization divorced from any human emotion or intuition.

Human Decision-Making: Looking Beyond Rules and Logic

While AI tackles poker as an exercise in logic, human players bring much more to the table. Human decisions are influenced by an alphabet soup of different factors:

  • External Observations: The opponent’s betting patterns, facial expressions, and table talk all feed into a player’s decisions.
  • Internal State: Mood, fatigue, or even the “phase of the moon” may affect decisions.
  • Adaptation: People dynamically adjust strategies according to both game states and psychological cues.

Example of Mixed Strategies in Action:

A player is on a tough call:

  • Folding means losing $10 for sure.
  • Calling can win $40 but comes with a 50% chance of losing.

By calling 50% of the time and folding 50%, the player maximizes expected profit while remaining entirely nondescript.

As an AI engineer, this probabilistic behavior would be reduced to math. For the human, though, it’s partly a logical process and partly instinct – a decision informed by years of experience and the feel for the moment.

The “Infinite Problem” Explained

There seems to be this assumption that poker is an infinite game due to its complexity. It is not, say AI engineers.

Why Poker Is Finite:

  • Mixed Strategy Simplifies Complexity: Probabilistic actions impose order on the decision-making process. An AI computes the expected profit created by many moves and finds the optimal strategy.
  • Finite Game State: While poker is a complex game with hundreds of variables, every decision is firmly bound by the rules of the game. Possible actions and their outcomes are high but finite.

Interesting Nuance:

Even such a minor detail as the size of the stacks at the start may have a twist. For example, a $600 starting stack might disturb a superstitious opponent enough to adjust their strategy. These seemingly insignificant details highlight the balance between pure logic and human psychology.

Strengths and Weaknesses: AI Versus Human Players
Continue reading →

901 Words

Adaptive nearest neighbor: AI for real-time data streams

Adaptive Nearest Neighbor Algorithms Revolutionize AI Decision-Making

Today, in every system, the features of streams of data are everywhere. Therefore, efficiency and effectiveness in the processing and classification of data streams are synonymous with success carved for many modern AI applications. In fact, from market analytics conducted by financial systems to the game of AI poker bots playing against human opponents, advanced algorithms require one very strong pre-requisite: real-time data processing.

ANNCAD, Adaptive Nearest Neighbor Classification Algorithm for Data streams, is the marriage between nearest neighbor classification and dynamic adaptability so that the system keeps its efficiency and correctly responsive, even while patterns in the data change.

Let’s have a look at how such a mechanism works, namely, ANNCAD, to see why it is or was the main bedrock underlying modern AI.

What is ANNCAD-adaptive nearest neighbor classification?

At its core, ANNCAD is a classification algorithm for data streams characterized by a continuous flow of data that needs processing in real time. Unlike the traditional classifiers working on a static dataset, ANNCAD updates itself dynamically for every change, hence assuring high accuracy even in case of a shift in the underlying data distribution.

Some key characteristics of ANNCAD are the following:

  • Multi-resolution data representation: ANNCAD allows for a variable-sized feature space partitioning for better classification at much higher efficiencies.
  • Incremental updates: ANNCAD can integrate incoming data points with very low real-time demands for complete retraining of the classifier.
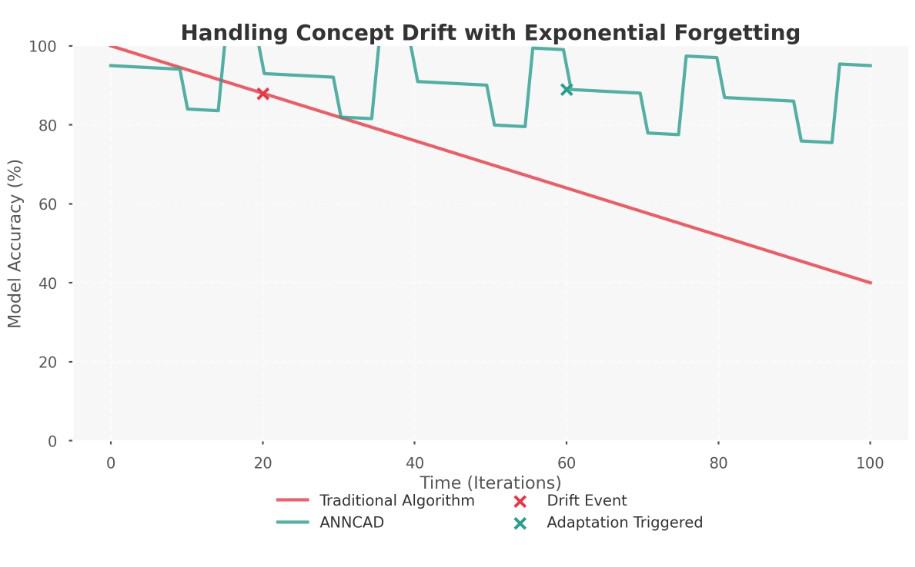
  • Handling concept drift: ANNCAD updates the model using an exponential forgetting mechanism where more emphasis is placed on recent observations.

This makes ANNCAD particularly fit for domains where environmental changes may be rapid, such as in gaming or financial analytics.

Main innovations of ANNCAD

1. Multi-resolution data representation: Traditional classifiers face the challenge of choice between high resolution versus high efficiency. ANNCAD models the feature space as a hierarchical grid, using finer grids in the densely populated areas and coarser grids in sparsely populated ones.

This allows for a great improvement in the accuracy of classification with very small additional computational overhead. This will enable the algorithm to delve into parts of the data stream that matter the most, skipping irrelevant or redundant information.

2. Incremental updates for real-time applications: In such dynamic environments, the classifiers need to learn continuously. In ANNCAD, this is made possible by the fact that newly arriving data gets seamlessly integrated into the classifier through incremental updates.

For instance, in an AI poker bot, the ability to perform incremental updates lets the system adapt to different changing strategies from an opponent-anything but having to retrain the system from scratch. This saves not only computational resources but also enables the system to make decisions in real time.

3. Handling concept drift: Concept drift-the changes in the underlying data distribution over time-is the most difficult challenge arising in data streams. ANNCAD addresses the challenge through an exponential forgetting mechanism where the algorithm gives more importance to the latest data while it gradually forgets the older information.

It proved to be significant in those areas that are characteristically fast-changing, such as financial market forecasting or developing new patterns of playing by gamers in online poker games.

Continue reading →

966 Words

How Monte Carlo sampling and regret minimization power AI

Try teaching an AI to play poker, navigate a robot through a boulder-strewn obstacle course, or make decisions in life-and-death situations for autonomous driving. How would a researcher ever develop an algorithm that would make near-optimal decisions in this complex and uncertain environment? Enter Monte Carlo Sampling and Regret Minimization-two large areas of modern artificial intelligence and game theory.

Some of the major techniques powering modern AI systems to compete, learn, and adapt in real time are discussed. Let’s examine exactly how such methods work, why they are so important, and what the future holds for AI-driven decision making.

Decision making challenge: large scale games and AI

Central to AI decision-making is the problem of optimal choice in various uncertain environments, ranging from two-player games like poker, through resource allocation in networks to navigation of robots.

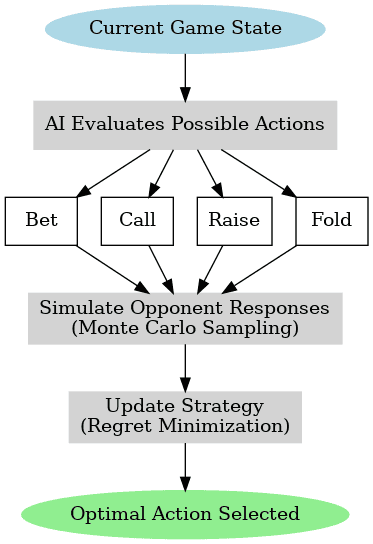
These activities involve modeling of such an environment as an Extensive form game since every decision may alter the future course. Again, MCS and RM are two handy tools in such games-reducing huge decision trees to such an extent that a few million scenarios can easily be processed by an AI.

Monte carlo sampling: predicting the future with probability

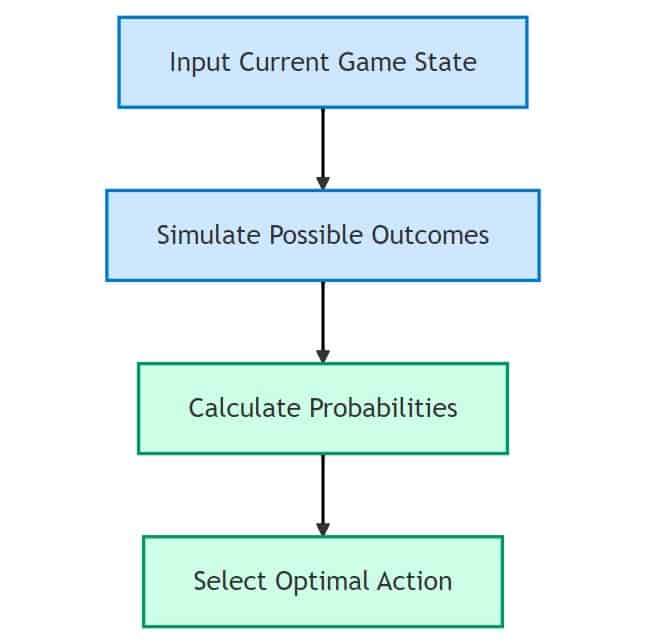
MCS is the process of playing out possibilities in your mind to decide on the best action. In other words, in short, it consists of the following:

  • Simulation of random outcomes: The AI makes random plays of the game and finds out what can happen in the various possible futures.
  • Building probability model: These plays combine to get a probability-based model of the environment.
  • Making data-driven decisions: Using the outcome of these simulations, AI makes the best decisions.

Example: MCS in poker lets the DeepStack and Pluribus bots experience almost millions of simulated hands, deeply understand possible risks and rewards.

Regret minimization: learning from mistakes

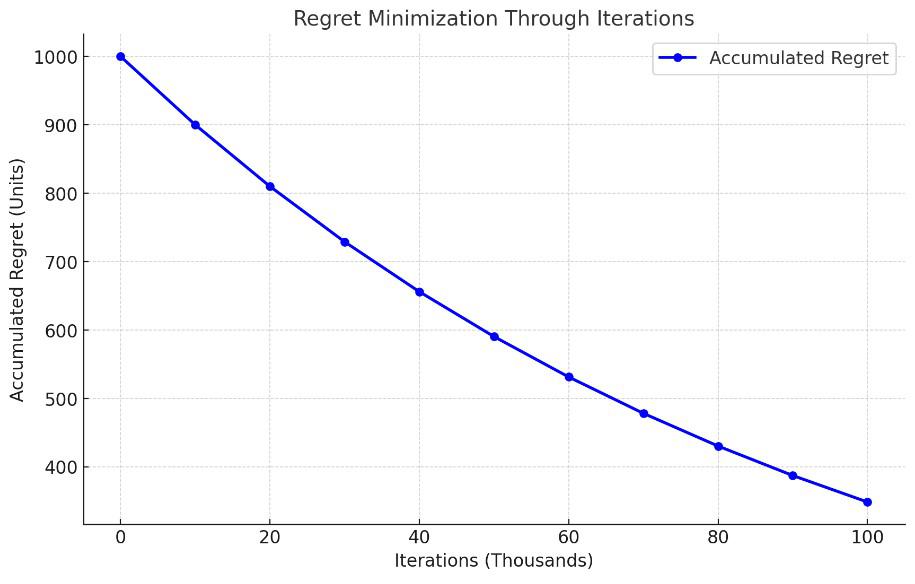
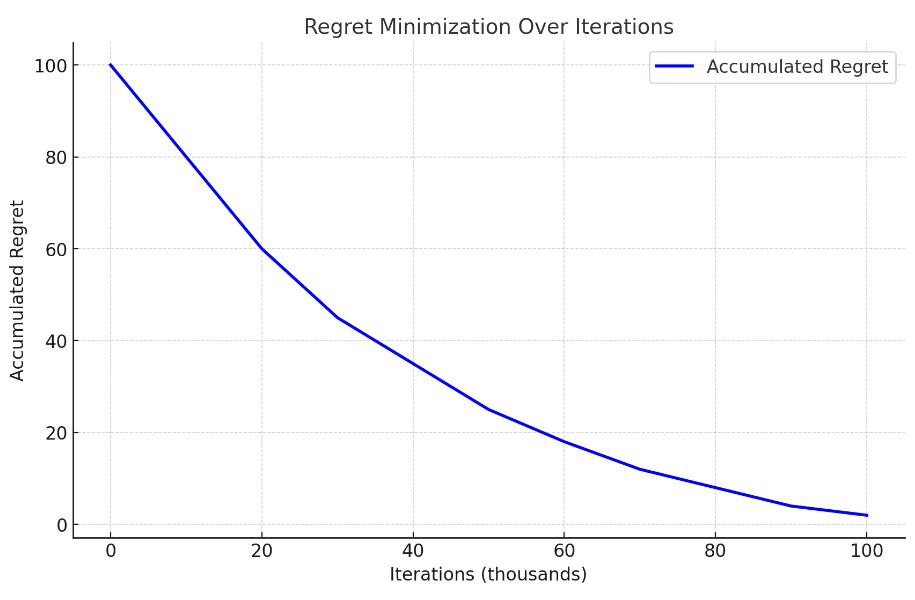
Where MCS predicts possible outcomes, RM ensures the AI will learn from its mistakes. The basic underlying idea here is to minimize regret for failing to choose in retrospect what appears to be an optimal action.

How it works:

  • Calculating regret: After every game round, the AI compares its action’s result to the best possible result.
  • Updating strategy: The AI adjusts its strategy, favoring actions that reduce regret over time.
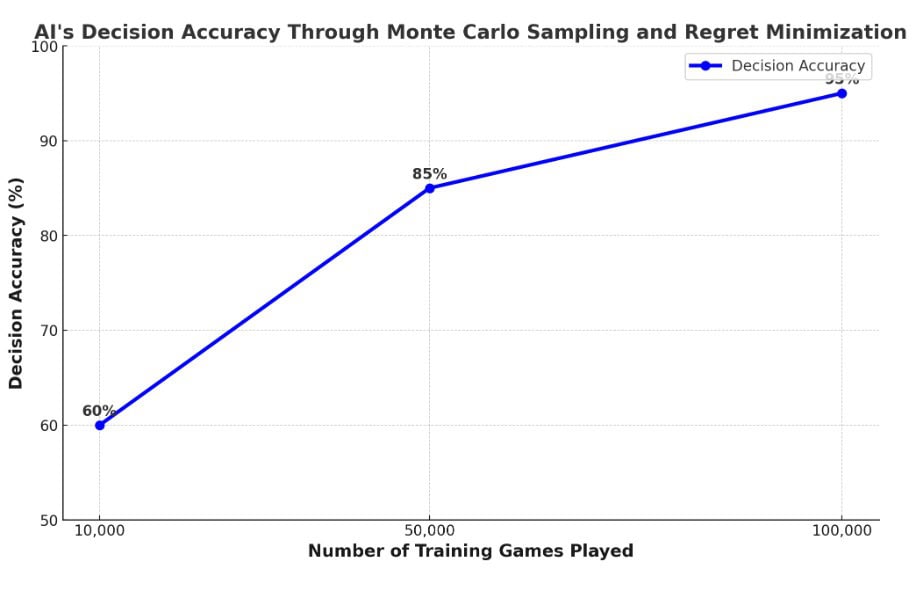
  • Convergence: As the AI plays more games, it converges toward a near-optimal strategy, ensuring long-term success.

Combining monte carlo sampling and regret minimization

The magic has been unleashing in their combinations. Monte Carlo Counterfactual Regret Minimization, from the work of Marc Lanctot, brought together Monte Carlo simulations and regret tracking to compute Nash Equilibria in complex games.

Main MCCFR Novelties:

  • Game abstraction: It tends to simplify big decision trees for game modeling.
  • Simulation-based learning: The strategy through the continuous refinement allowed by simulated gameplay hands for solving allows learning even in incomplete information settings.
  • Real-world applications: From poker bots to self-driving cars, MCCFR models will make AI even more cunning, faster, and hard to beat.

Why it matters: applications of AI decision-making in real life

  1. Poker and competitive games:

MCCFR studies gave rise to AI poker-playing bots like Pluribus and DeepStack. By building a computation over millions of outcomes and iteratively updating the playing strategy based on game adversaries, it could master even the most complex plays.

  1. Robotics and autonomous vehicles:

Decision-making finds its major application in pathfinding, obstacle avoidance, and multi-agent collaboration in robotics. MCTS enables a robot to decide on how to navigate through an uncertain environment by considering various future paths that the robot may take.

  1. Financial markets and trading bots:

The stock trading bot uses these techniques to conduct market data analysis, predict, and generate trades for minimum risk and maximum return.

  1. Healthcare and medical decision support:

AI diagnosis tools employing regret minimization offer optimal treatment plans with previous patient history and minimize the chances of errors in medical decision-making.

Looking ahead: the future of AI in decision-making

Monte Carlo Sampling and Regret Minimization will play an evermore greater role when AI-powered decision-making becomes ever more advanced. Developments will very well include:

  • Fully adaptive AI systems: Those learning in real time from actual live interactions.
  • AI-powered negotiators: These shall work out more refined algorithms for conflict resolution and complex negotiations.
  • Global AI deployments: From disaster response to strategic defense systems, game theory-inspired AI will reshape our world.

Final Thoughts

In practice, understanding how monte carlo samplings and regret minimizations work opens insight into just how mathematically creative some of today’s smartest AI really is. These are techniques that not only redefine what AI can do but show how machines can learn, adapt, and master even the most complex human-like tasks.

And it would ostensibly never end, since choices for intelligent and efficient decisions keep on coming with every step in AI. From poker to real-life, monte carlo sampling combined with regret minimization is the magic sauce taking AI places.

803 Words

Mastering poker AI with Restricted Nash Response


Probably among the most complex questions of game theory can be viewed regarding how to develop AI that would be able to adapt against an unknown opponent and at the same time not be vulnerable to him. Among those, the Restricted Nash Response has to be regarded as a step-change approach able to balance two critical objectives of poker AI development: to exploit the weakness of an opponent while being defended against possible exploitation by more skilled adversaries.

Put together with inputs from Game Theory, this has polished RNR to near-perfect play in poker AI. This allows for real-time adaptation-while the integrity of the strategy remains intact-thus, such an approach is highly valued both for competitive play and for AI research.

What Is Restricted Nash Response (RNR)?

The RNR represents a rather complex algorithm. It improves decision-making through a reduction of the search space within a game tree. Classic Nash Equilibrium algorithms try to cover the entire game tree, which gets prohibitively costly computationally. On the other hand, RNR limits its attention to respective game states in which huge payoff gains due to the exploitation of opponents may be realized.

This will be lightweight because the narrow selective approach will not overcomplicate things, with very little cost in competitiveness. RNR is scalability- and efficiency-baked, suitable for rapid environments, such as may be the case in online poker tournaments.

Key principles of RNR

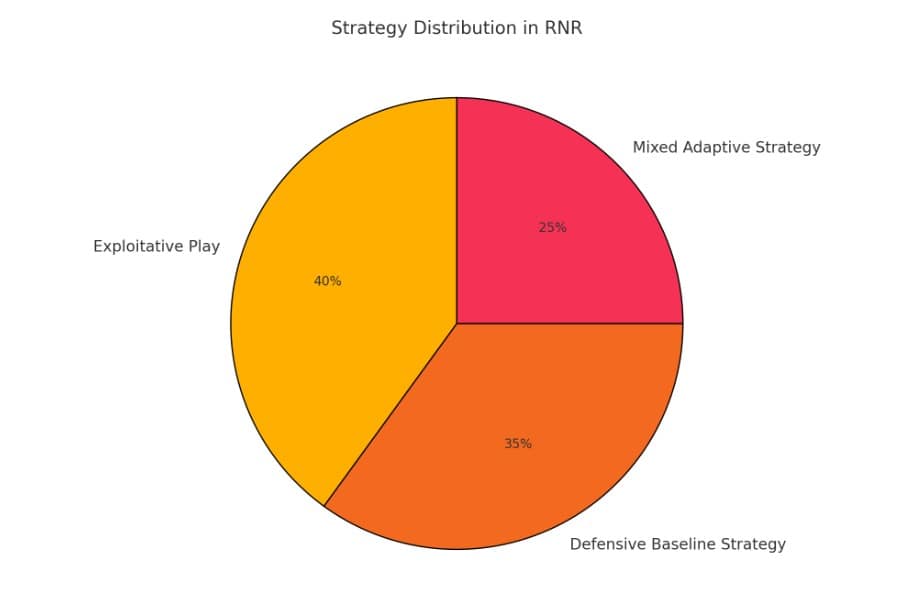
The RNR works on three mainstays to make sure there is dynamic adaptation with optimization of computational efficiency:

  1. Limited search space:
  • This will cut computational complexity because it runs RNR on only meaningful branches of the game tree; improbable or otherwise irrelevant branches are just ignored, hence allowing real-time play with no strategic compromise.
  1. Opponent exploitation:
  • By observing the opponent’s bet-sizing pattern, bluff frequencies, and fold rates, RNR picks up their exploitative weaknesses. Whenever such a pattern comes again, this is where the AI is going to maximize the Expected Value by acting accordingly.
  1. Defensive strategy:
  • If no weaknesses are found, it always resorts to using an unused move due to Nash Equilibrium considerations that guarantee survival in the long term, offering the least number of exploits to any opponent, let alone really cunning ones.

How RNR Works in Poker AI

RNR finds its application in Poker AI in a stepwise manner to optimized decision-making through observation, adjustment, and calculation of response. These shall include:

Step 1: Opponent modelling based on information acquisition

Based on this observation, an opponent plays a number of plays that may include:

  • Betting patterns: the frequency at which opponents bet into a situation;
  • Bluff frequencies: the ratio of bluffing versus calling;
  • Fold rates: the frequency of folding to pressure.

From here, the AI does the modelling of an opponent by carrying out a bounded game tree incorporating only the most important game states.

Step 2: Creating a limited game tree

Further, AI prunes a game tree in the following way:

  • All actions whose probability is close to zero get eliminated.
  • Of all the other positions, consider for decision-making only the most strategically central points in detail.

This is how it decreases the total number of all the possible variations of the events, allowing AI to focus more resources on the really important ones.

Continue reading →

982 Words

AI in Online Poker: Nash Equilibria and Optimization

The Power of AI in Online Poker Strategy

It used to be that online poker had a strategy, but things flipped with artificial intelligence coming in. It is now that there is a set of developed algorithms that implements various techniques, including Nash equilibria and gradient optimization, toward the finetuning of gameplay. Thus, this should balance the general aggressiveness with caution in developing robust yet adaptive strategies.

These are some state-of-the-art approaches which developers in poker bots rely on. Gone are those simple hacks at poker. Deep AI systems, based on that kind of theory-DeepStack AI, and Pluribus poker-regularly defeat even the best human player.

What does the Nash Equilibrium mean in poker, exactly?

The Nash Equilibrium is that point at which no player is able to get better payoffs by a unilateral alteration of strategy. In poker, it would be the simplest example: AI plays so that nobody can exploit it.

Here’s why this matters:

  1. Unexploitable play: AI systems use Nash equilibria in hope that even the best of human players cannot exploit them while playing.
  2. Balanced strategies: AI, on an optimal level, then does the balancing of betting, calling, and folding for most profit in the long run.
  3. Dynamic adaptation: Modern systems operate under Nash principles, in dynamic environments. Examples abound, from multi-table tournaments.

Whereas the unsophisticated poker cheat would rely on rigid and unbending rules, in the Nash-based AI system, modifications are done dynamically by considering opponents. This is indeed the very framework PokerAlfie uses to rout ultra-high-stakes games.

Place of Gradient Optimisation in Poker AI

Gradient optimization is really just fine-tuning strategies in small, incremental improvements. Consider having a poor strategy to begin with; methods of gradient look at every little decision and slightly adjust to slowly hone in on an optimal playstyle.

Examples are like a poker AI bot, which, on a very rudimentary level, can start with quite a simple decision tree. With experience, through gradient optimization, this will learn to adjust its game in light of:

  • Opponent tendencies.
  • Historical hand results.
  • In-game, real-time dynamics.

That is quite effective in those very cases where nothing else could work, like the so-called poker cheat sheet. Gradient optimization will ensure that AI chooses the most optimal play and adjusts in the process to opponents’ strategy changes.

Combined Nash Equilibria and Gradient Optimization

It is in combining these techniques, however, that the true power of AI really starts to come into being. The Nash equilibria give very strong theoretical underpinning, while the gradient optimization keeps it improving. Put together, they tend to create unbeatable AI systems.

Let’s break it down.

  1. Base strategy: A theoretically un-exploitable strategy in the very beginning, in game-theoretic terms-such as Nash.
  2. Adaptation (Gradient): The system adapts this prior to exploit particular opponents or situations.

This is a synergy that creates considerable ease for an AI system, like DeepMind Poker Bot, to create great results both in theoretical and practical play-a sizeable proportion beyond any poker machine hack.

Applications in Online Poker

  1. Tournament play: In such an unstable environment as WSOP is, AI systems try to succeed with the help of the Nash and gradient methods. This way, AI can compete even with very aggressive or unpredictable opponents.
  2. Training tools: Most of the training sites base their functionality on these algorithms, fine-tuning a player’s strategy. Such tools can be much more indicative about this than standard poker hacks.
  3. AI vs. AI: In games between online poker bots, Nash-based strategies ensure fairness and balance, while gradient optimization fuels improvements.


Continue reading →

890 Words

Monte Carlo Restricted Nash Response: optimizing AI in poker

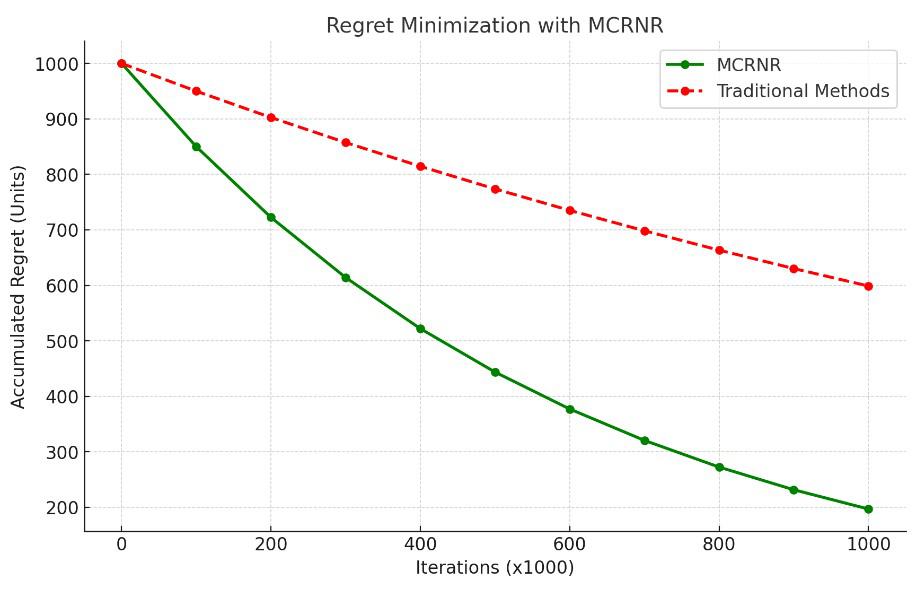
Poker, with incomplete information, has become an ideal testbed for advanced AI research where the players consider finding moves with complete disregard for any idea about the held cards of their opponents. Probably among the most important, critical concepts that have emerged in AI poker is MCRNR – Monte Carlo Restricted Nash Response. Combining regret minimization with Monte Carlo sampling, this convoluted algorithm results in near-optimal strategies that find adaptiveness while decreasing computation complexity.

MCRNR has expanded the bounds on what AI is capable of achieving with strategic decision-making; it is hence a critical milestone for developers who want to create sophisticated poker bots and AI-driven decision-making systems.

What is Monte Carlo Restricted Nash Response?

MCRNR: Monte Carlo Restricted Nash Response-An extended version of an algorithm to solve extensive-form games, such as poker, by computation of near-equilibrium strategies via selective sampling. Current approaches necessarily have to explore the whole game tree, which is computationally infeasible; MCRNR tightens the focus by having two major components:

1. Restricted Nash Response (RNR):

  • It computes the best response to a limited sub-set of strategies.
  • Focuses on just high-probability game flows and skips unlikely game paths.

2. Monte Carlo Sampling:

  • It randomly samples the game states of the large game tree.
  • Evaluating over the most relevant nodes reduces computational overhead.

By combining these methods, MCRNR efficiently approximates Nash equilibrium strategies while minimizing memory usage and processing time.

How MCRNR works in Poker AI

Step 1: Opponent modeling by sampling

  • It does so by observing opponent action through Monte Carlo simulations, generating probabilistic models which estimate the probability of several plays given the observed behaviour.

Step 2: Heuristic game tree search

  • MCRNR uses RNR to find the important branches instead of calculating the complete game tree. During selection, it will focus on the choice of action that offers the highest expected payoffs, disregarding implausible cases.

Step 3: Best response under regret minimization

  • MCRNR tracks counterfactual regret, which is the estimated amount the player could have done better if they had chosen differently. Then it updates its strategy, after the end of each simulated hand, to minimize this regret.

Step 4: Refining the adaptive strategy

  • By repeated simulations, MCRNR keeps refining its strategy-keeps converging to a Nash equilibrium but always remains flexible with opponent-specific adjustments.

Why MCRNR changes everything in Poker AI

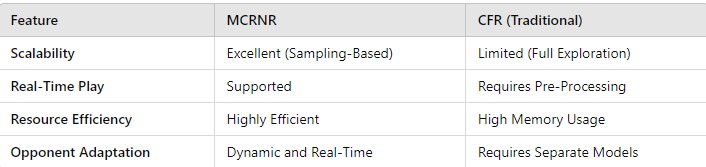
MCRNR excels where traditional algorithms like CFR (Counterfactual Regret Minimization) face limitations. Its unique advantages include:

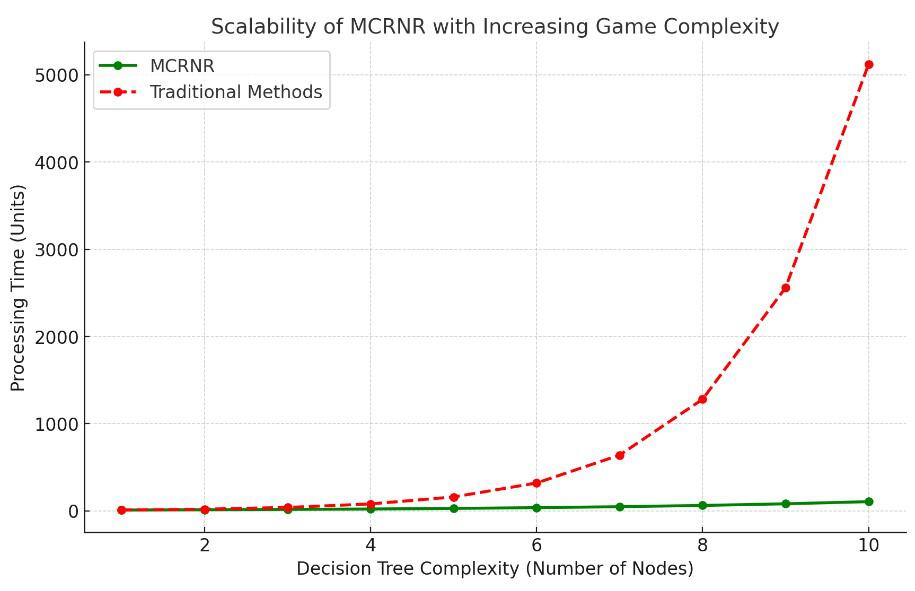
1. Scaling to large games

  • Poker’s hugely vast game tree makes exhaustive exploration impractical.
  • This vastly reduces the search space by MCRNR through its sampling-based approach, making complex multi-player games tractable.

2. Real-time decision-making

  • By considering only relevant game states, MCRNR allows for real-time play with severe time bounds.
  • It sees broad application in major tournaments and competitive Internet poker.

3. Memory and processor efficiency

  • Unlike most of the memory-intensive methods that require pre-computation of the strategies, MCRNR dynamically builds and updates its game model with less memory and computation.

MCRNR Applications with Poker AI

1. Training simulations

  • MCRNR lets developers simulate millions of poker hands to make strong AI opponents that can play under every possible condition.

2.Opponent exploitation

  • Its adaptive capabilities enable MCRNR to exploit a weak opponent fully while being balanced for strong players.

3.Multi-player strategy development

  • While many of the AI systems suffer with multi-player dynamics due to game tree complexity, MCRNR excels by focusing only on the most critical interactions.

Comparison with Classic Poker AI Algorithms

Future development in AI Poker using MCRNR

The potential of MCRNR actually goes well beyond poker. Some future applications could be:

1. Hybrid AI models:

  • It can be further improved when combined with MCRNR neural networks, hence enhancing its predictiveness and potentially allowing application to complex games.

2. Multi-player optimization:

  • Extend capability of MCRNR to multi-player strategy prediction and cooperative game.

3. General AI applications:

  • Example applications of MCRNR include financial modeling, automated negotiation systems, and real-time decision-making applications both in business and cybersecurity.

Conclusion

The Monte Carlo Restricted Nash Response is another big leap in AI poker strategy. Essentially, by incorporating the elements of regret minimization with Monte Carlo sampling, it thus provides almost optimal gameplay at less computational cost.

Be it developing the world’s best poker bot or researching AI-driven decision-making, MCRNR constitutes a strong framework for obtaining scalable, adaptive, really effective strategies. The future big move in AI poker has already been played-already time to see what’s next?

720 Words

Fast Bundle Algorithm: Optimizing AI Poker Strategies

Online poker has always been one of the most challenging areas for artificial intelligence because of its deep decision trees, imperfect information, and ever-changing strategies. Such a domain needs algorithms with powerful and similarly flexible capabilities. The most important discovery which was uncovered through it was a fast bundle-based anytime algorithm; this technique exploits both dual oracles and regret minimization to solve complex game-theoretic problems in a very effective way.

This is an algorithm that has already changed everything in poker AI in terms of real-time decisions, better resource allocations, and convergence much faster towards the best strategy. But exactly how does it work, and what does it mean for the developer of Poker AI? A little deeper dive into the mechanics involved; let’s explore its application.

What is the Quick Bundle-based Anytime Algorithm?

At its very core, the Fast Bundle Algorithm solves large-scale optimization problems; more specifically, extensive-form games, such as poker. Algorithmically, it works as described below.

Divide the game into sub-problems

  • It chops a huge game tree into small bundles-or sub-problems-easier to handle.

Dual oracles

  • A dual oracle predicts the likely actions of the opponent given past decisions made.
  • This prediction decreases exhaustive searches by narrowing down the search field to only relevant game states.

Minimize Regret

  • The algorithm defines “regret” – how much it regrets not playing the best move after many iterations of game playing.
  • It updates its strategy to minimize regret with iterations, thus trying to be more accurate at each step.

These combined techniques make the fast bundle algorithm uniquely suited for decision-heavy environments like online poker.

How It Goes in Poker AI

1. Game tree reduction

Poker has a very large game tree, comprising billion of possible game states. The fast bundle algorithm groups in and bundles similar game states into segments, making them computationally more feasible to work with, thereby allowing real-time decisions even by using a small computational resource.

2. Optimal response calculation

Using these two oracles, AI predicts the sequence of moves most probably played by an opponent according to history and then computes the optimal response strategy in its light, rather than analyze the whole game tree.

3. Minimisation of action regret

It does so by iteratively updating its strategy after playing a number of simulated hands, then updates based on computed regrets. Rebalancing of the strategy takes place at times when AI continuously loses at certain states of the game to reduce the further potential loss.

Key merits of the fast bundle algorithm

1. Speed and efficiency

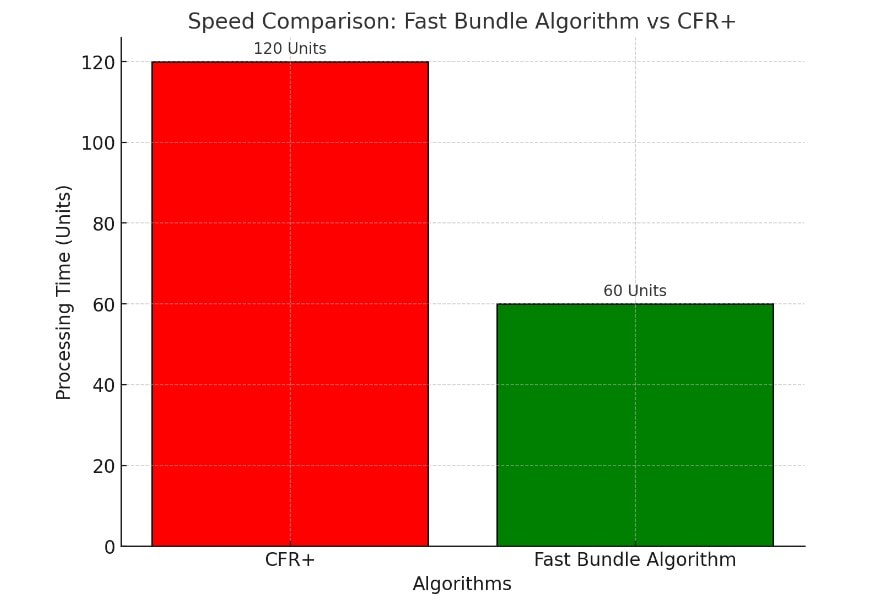
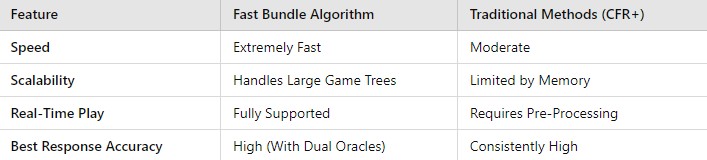
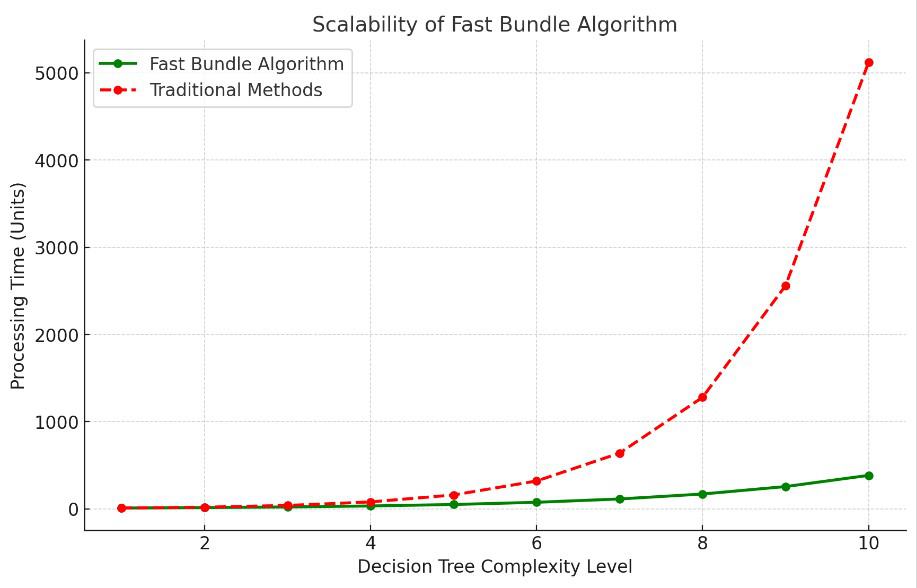
In contrast to conventional game-solving algorithms, such as CFR (Counterfactual Regret Minimization), fast bundle unlocks game states at a much faster clip. It reduces unnecessary computations by avoiding unlikely game scenarios.

2. Scalability for large games

Poker games with millions of possible combinations become more manageable due to the algorithm’s ability to split the game tree into bundles. This makes the approach suitable for both heads-up and multi-player poker environments.

3. Real-time decision-making: 

The algorithm supports real-time decision-making, enabling AI to adjust its play during live games without requiring long pre-computation periods.

Applications to Poker AI

  1. Opponent adaptation in real-time: Fast bundle algorithms can support AI in dynamic adaptation in real-time towards the opponent’s change in strategy. Therefore, they are quite effective in tournaments.
  2. Advanced training simulations: This algorithm helps developers in creating a strong environment for training where AI would simulate millions of hands with different playing styles and thus build better strategies over time.
  3. Multi-player strategy development: While many poker algorithms struggle with multi-player games due to exponential complexity, the bundling process simplifies calculations, making multi-player AI feasible.

Comparison with traditional algorithms

Challenges and limitations

While the fast bundle algorithm excels in many areas, it also has its limitations:

  1. Data dependence: The performance of an algorithm would highly depend upon previous data of game playing. The algorithm may not work efficiently in unfamiliar scenarios.
  2. Manage complexity: Too aggressive bundling does not guarantee to avoid oversimplifying the gametree, hence a suboptimal strategy.
  3. Ethical considerations: Powerful AI in online poker is considered an ethical concern about fair competition, because some platforms use AI detectors.

Future Development in AI Poker

The Fast bundle algorithm is just the very beginning. Further research can take AI poker strategies to entirely new levels. Following are some of the promising directions:

Continue reading →

1,001 Words

How a “New Algorithm” revolutionizes poker and convex games

Poker was never about luck; rather, it’s a game of strategy and psychology intermingled with well-judged risks-a true test of reading one’s man and calculating odds. Give this centuries-old game to cold, calculating, and exacting algorithms in a play to outperform even the most brilliant human players. That is just what the researchers, H. Brendan McMahan and Geoffrey J. Gordon, do by proposing one revolutionary method of solution for such complex games as poker.

It proves the basis of the very first blazingly fast, bundle-based anytime algorithm that plays poker-but actually reopening how we think of strategy in incomplete information games.

Beyond cards, what is a convex game?

But before that, let us take a step back to really appreciate the genius of this invention. Poker is what mathematicians call an “extensive-form game.” It’s like a tree: All the possible moves and all counter-moves are its branches. Add some hidden cards and randomness, and soon it becomes computationally overwhelming-a nightmare for all kinds of traditional algorithms.

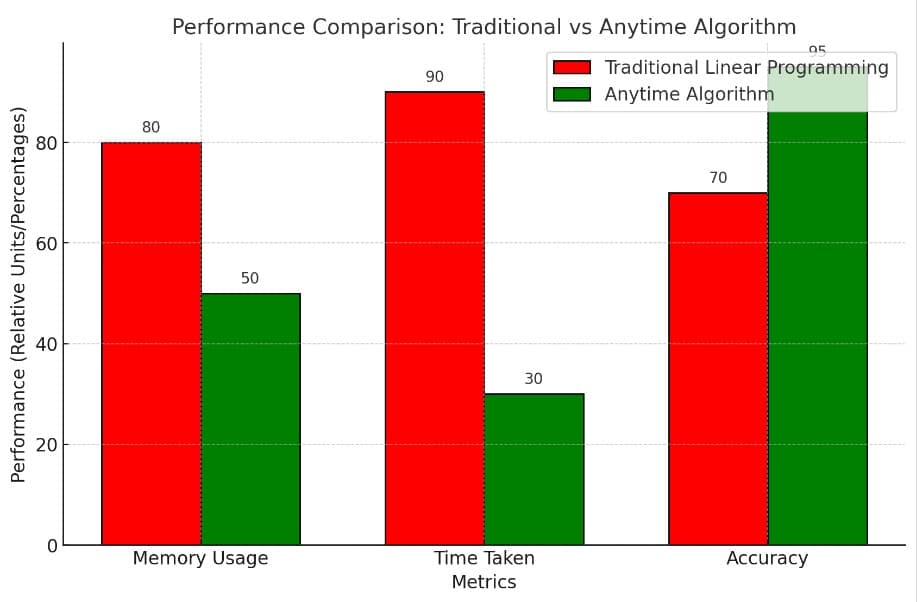
But poker is only the beginning. The broader class it falls into, convex games, is even more complex: a family of games of optimization against a constantly shifting tapestry of possibility, with each opponent’s every move twisting and turning the strategic topography afresh. For years, game theorists had sought to solve such games by expensive methods such as linear programming, which sometimes takes days and sometimes takes weeks to achieve a solution.

Enter the Anytime Algorithm

Unsatisfied with the old ways, McMahan and Gordon set their minds on doing things a little differently. Why wait four days for a solution when you could get an optimal answer in two hours? Their algorithm also runs smarter, dynamically modeling the game using “fast best-response oracles.”

Think of it as playing poker while learning the rules and finding the quickest path to victory all at once. The model is nowhere near static; it’s continuously evolving towards what seems like the most promising directions for further exploration.

Once it picks a direction to go in, it dives right in, optimizing as deep as lasers. The result is a rather accurate solution, yet it comes out so considerably simple. Best of all: It does it all using less than 1.5GB of memory, less than the average smartphone uses to run Instagram.

The poker test: Texas Hold’em versus AI

It is for the purpose of testing the powers of the algorithm that Texas Hold’em Poker has been chosen-a favorite of developers in AI for the balance between strategy, psychology, and luck. Only this was not a completely full-fledged multi-player poker game but a simplified version, deeply mathematical in its essence.

The results were astonishing: The algorithm approximated the value of the game to within $0.20 of perfection with a maximum pot size of $310-for comparison, the previous state-of-the-art algorithm using linear programming took more than four days and required 25GB of memory for the same degree of accuracy.

Why it matters outside of poker

But even if poker isn’t your game, the ramifications of this research extend far from the card table: convex games are everywhere, from economics and military strategy to logistics and the design of autonomous vehicles. The work by McMahan and Gordon can revolutionize the process anywhere a decision has to be made under uncertainty.

Take disaster response, for instance, where very rare resources have to be allocated with regard to effectiveness and speed. Traditional algorithms would take such a long time to reach the global optimum that the solution became irrelevant. This algorithm slices through the complexity and provides real insights in a fraction of the time.

Continue reading →

816 Words

Using Hidden Markov Models to Improve Online Poker AI

The application of a hidden Markov model in strategy for AI Poker: Online poker is essentially an incomplete information game where every decision depends upon the subtle pattern and the hidden dynamics. Artificially intelligent machines require very advanced machinery in mastering this complexity. Within these lines, the HMMs are amongst one of the strongest frameworks that help in analyzing sequences of actions and predict further strategy by opponents.

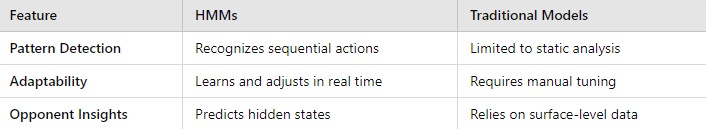
Unlike other more simple poker hacks based on certain set or static rules, HMMs are dynamic; they change in real time. They enable the AI to identify patterns in the betting behavior and hence spot bluffs or predict further moves. With this value, the HMMs are the backbone of even those very advanced poker AI bots operational up to date.

What is a hidden Markov model?

HMMs are statistical models of processes where the signal or observation results owing to an underlying state, which isn’t directly observable. In poker now, this takes over to “an opponent’s hand strength” as “hidden states,” and “his bets, raises, and folds” as “observable outputs.”

How it really works:

  1. States and observations: That is, the states are finite-a strong hand, a weak hand, a bluff-associated with observable actions.
  2. Transitions: the probabilities of transition to other game states. He’s on a good hand so he is most likely to raise rather than fold.
  3. Training: This is where AI is trained with historic data to learn those very probabilities and then make correct predictions during the live game.

That’s where HMMs take a catch on the base poker cheat sheet-like tools that just can’t learn.

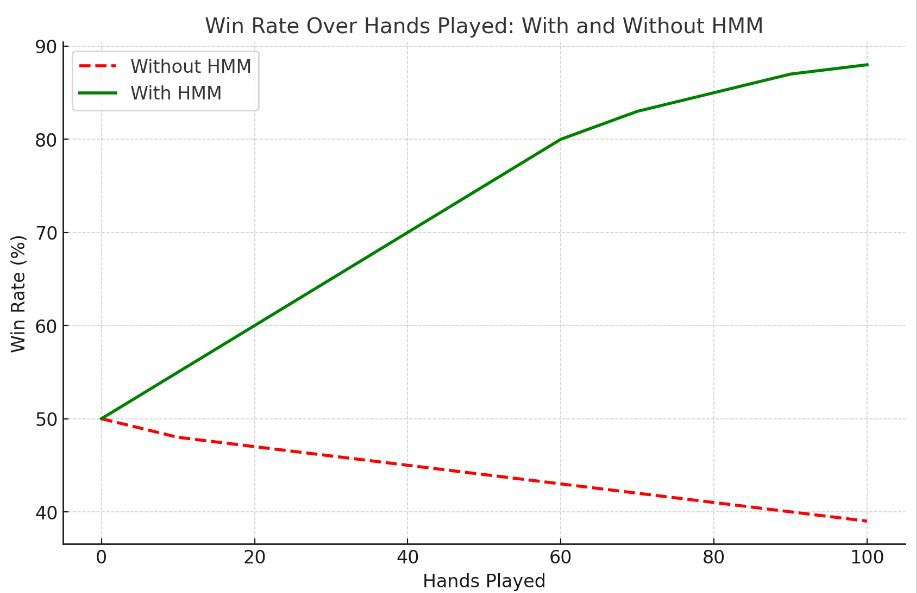
Enhancement of the AI poker tactics by using HMMs

  • Pattern recognition

It is in these very sequences of actions that HMMs tend to excel; a good example could be given where opponents who, at a flop bet, tend to be really aggressive and fold a lot at the river. It is these sequences that are looked upon by HMMs; hence, through AI, it can classify the opponents and change its strategy.

  • It will be tighter playing against super LAG so as not to get trapped.
  • If opponent is cautious AI will very much probably bluff in order to make him fold.

It’s the dynamical approach which differs from usual poker online bots through advanced systems such as pluribus poker.

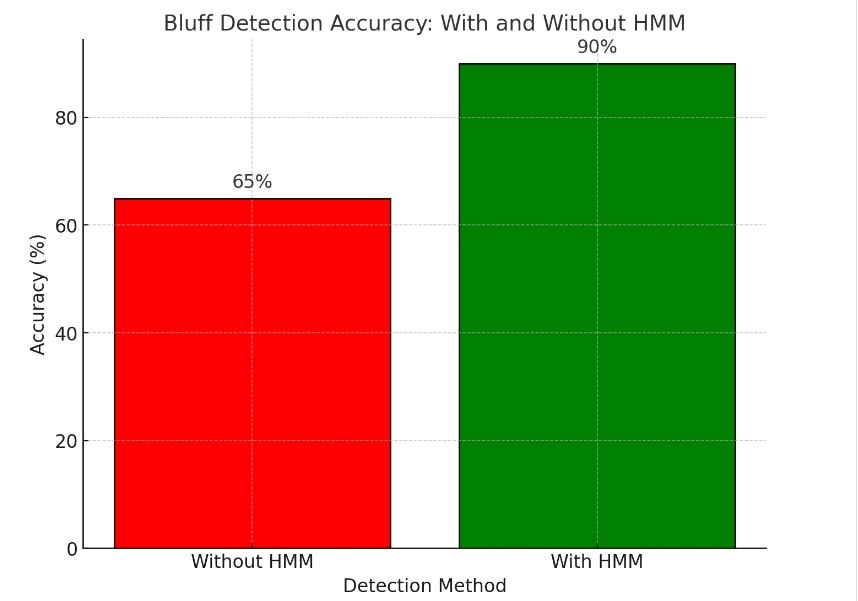
  • Bluff detection

As it is not that easy to catch, and in the end, the bluff belongs to a poker game. Due to considering a betting pattern and timing, an estimate can be made by the HMMs regarding the suitability of playing behavior given the probable hand strength of a player.

For example, if one player is disproportionately raising concerning the board texture, then the AI would classify that correctly as a possible bluff. Unlike any simple poker hacks involving fixed and fast rules, the HMM-based AI would learn those kinds of subtleties.

NO

  • Opponent modelling 

Yet another set of applications of HMMs are in opponent modelling: training over historic hands allows AI  to make a good prophecy about what the opponent is most likely to play. As an example of this, HMM might pick up, for instance, that some player bluffs 30% on turn if check-raised. In that way, it will way easier for AI even to make more informed decisions even at very tense moments.

Applications of HMMs to Online Poker

  1. Real-Time analysis: HMMs can enable AI to analyze hands as they are unfolding and deliver an insight applicable at any moment in the game. This means players will make increasingly intelligent decisions in real time, especially those making use of online poker sites such as Poker AI.
  2. Practice platforms: With HMMs, one can practice with various types of opponents, either human or online poker bots.
  3. Tournament play: Actually, such developed HMM-based AI has done wonders in certain buy-in events at WSOP with variance in style of playing.

HMMs as compared to other AI models

Continue reading →

928 Words

How AI Solved Heads-Up Limit Hold’em: The CFR+ Revolution

The year 2015 marked a milestone in the history of poker when an artificial intelligence program called Cepheus “solved” an important variant of Texas Hold’em-namely, two-player Limit Hold’em-operating at its heart through an algorithm termed Counterfactual Regret Minimization Plus, shortened as CFR+. This AI showed that incomplete information games could, in fact, have mathematically optimum play.

While to the enthusiasts of AI and to the poker players, that day became the touchstone of strengths of the modern algorithms, for a poker cheat-it was the intellectual roadmap of how to create robust non-exploitative strategies, an implementable plan. It wasn’t about poker; it was a jump forward into how machines think, adapt, and learn.

What does it mean for a game to be solved?

In a game like HULHE, to “solve” means to devise such a strong strategy that no opponent can do better on average no matter how well he may play. Yet another way to look at it is that this Nash equilibrium prevents even the best players from doing more than breaking even over the long run.

In poker terminology, solving HULHE involved investigation into:

  1. Game states: Any and every possible decision point in the game, from pre-flop to river.
  2. Counterfactual regret: The amount of value lost by playing sub-optimally in any decision.
  3. Iterative refinement: Repeatedly adjusting strategies to minimize regret and approach equilibrium.

Such tools as CFR+ do not do any pure calculations but employ advanced heuristics instead to process efficiently trillions of game states; only this can give the level of precision beyond common poker hacks or simplistic poker cheat sheet-like strategies.

How CFR+ works

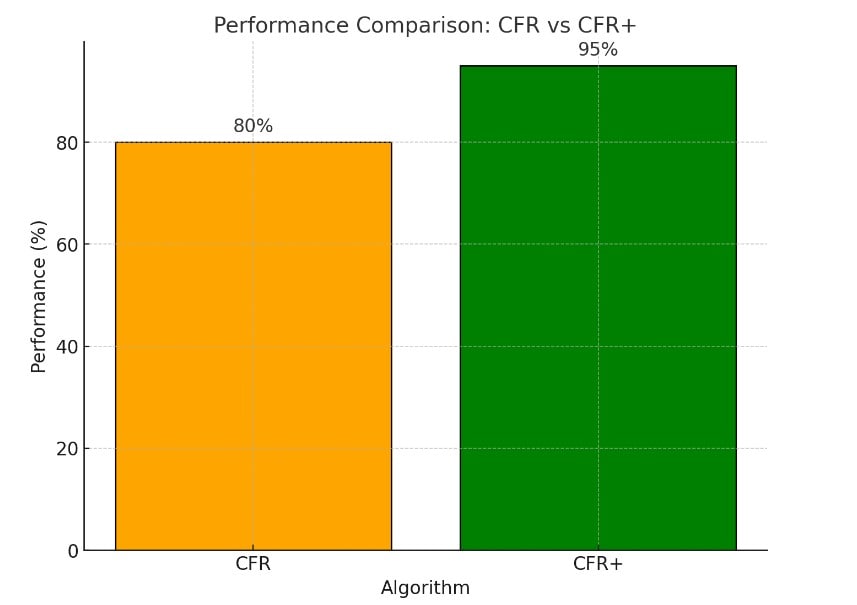
CFR+ is an extended form of the basic algorithm for Counterfactual Regret Minimization, converging faster and using less memory. Basic idea:

  1. Computation of regret: It calculates the regrets of all possible actions in a game state.
  2. Strategy shifting: The received actions obtain less importance with higher regret; the optimal actions win importance.
  3. Iterative improvement: The process is iterated millions of times, where each step keeps fine-tuning the strategy further.

When Cepheus finished training, it had tabulated over 24 trillion hands, enough to devise a nearly perfectly optimal strategy for HULHE; whereas even the strongest poker bot before the development of CFR+ could only approximately determine the best course of action.

Applications of CFR+ beyond HULHE

Everything in CFR+ is much more powerful compared with poker.

  1. AI training tools: Most of the poker AI bots are based on CFR+, which provides unexploitable strategies to be tested by a player.
  2. Game theory research: The algorithm improves the understanding of application areas such as economics, cybersecurity, and negotiation.
  3. AI strategy development: The researchers further develop more versatile AI in adapting the games to CFR+.

Online poker players depend on poker online bots that, increasingly-and poker ai online-are based on the principles of CFR+. From the DeepMind poker bot right up to PokerAlfie, it seems modern AI is dependent upon CFR+.

What Makes CFR+ Unique?

Salient features of CFR+, among others, are:

  • Efficiency: The algorithm uses very minimal memory and processing compared to the previous algorithms.
  • Scalability: CFR+ applies to large game trees and is therefore suitable for complex games, such as NoLimit Hold’em.
  • Precision: The algorithm always converges to a Nash equilibrium, hence strategies produced are unexploitable.

Continue reading →

927 Words