Every so often I’d catch myself mid-hand wondering: just how does this poker AI tool actually work, beyond the hype? A voice narrates, and it nudges me further. I remember my first introduction to DeepStack’s deep counterfactual value networks-poker AIs that could condition on distributions of hidden hands. That put poker AI, poker bots and poker AI research on the map. Now there’s Supremus. Let’s tell that story with missteps, and a human spark.
(Author’s note: I didn’t think so at the outset.)
Reimplementing DeepStack and noting flaws in poker AI development
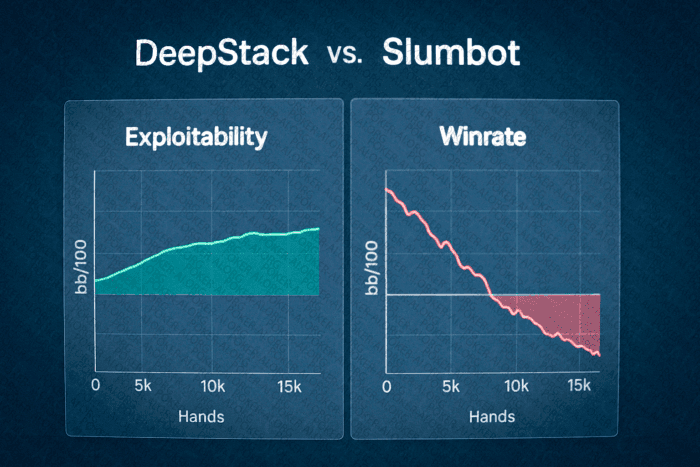
The reimplementation of DeepStack in practice loses to Slumbot. I observed data: reimpl lost 63 mbb/g to Slumbot despite still having low exploitability. That contrast became one of the first real-world lessons in Supremus poker AI research, where raw theory met practical results. That paradox struck me as strange – low exploitability yet losing all the time. I noted human-like error. Author’s note: I have always wondered why deep counterfactual value networks had not become more commonplace. That’s because the version of DeepStack lacked head-to-head strength, even though it was a milestone in the development of poker A.I. software. That made me question whether AI poker techniques provided any actual edge beyond theory.
Upgraded CFR variants and richer search: the birth of Supremus with improved poker AI algorithms

Next was the tweak of DCFR+, which increased the rate of convergence. Instead of the quadratic weighting of classic CFR, they deferred policy averaging and used linear weight for clearest results. So they updated both players at the same time and observed faster learning – very much not expected. Author’s note: That was like whittling away at an opponent until they cave. Supremus augment vanilla CFVnets with neural network value functions at the end of each lookahead. That made poker AI strategies more clear. This is not poker cheat or learning to cheat at poker or even poker cheat sheet; this is actually learning machine learning at the poker table.
GPU acceleration and massive training: how poker AI tools scaled
Supremus ran fully on GPU. It went through 1,000 DCFR+ iterations in 0.8 seconds, six times faster than DeepStack. This was a breakthrough moment in Supremus poker AI research, allowing large-scale strategy refinement in record time. The speed meant they could slash exploitability to 3 mbb/g over 5,000× quicker. Training data increased all of the following numbers are in the millions: River network trained on 50, turn on 20, flop 5 mil, auxiliary 10. Compare that to the relatively smaller number of examples used by DeepStack – the flop validation loss fell, from 0.034 to 0.011. I sensed the change – Supremus had turned into a beast of machine learning in poker. Author note: If you can imagine teaching poker bots billions of hands instead of thousands.
Supremus against Slumbot and beyond best poker AI performance
Supremus won 2.6 million chips over 150,000 hands-176 ± 44 mbb/g. DeepStack lost 63 mbb/g. Supremus doubled the profits relative to those of DeepStack. Which made it the best poker AI out of the bots. No speculations about “what if” – just the numbers, unambiguous wins. Performance speaks. We substitute “if DeepStack had done X” with observations. We see Supremus dominates.