Heads-up Limit Holdem Poker is Solved (thanks to CFR+)

In 2014, researchers at the University of Alberta used their CFR+ algorithm to successfully solve this poker variant, which is quite impressive. They analyzed 3.19×10^14 decision nodes! This would be like trying to count all the stars in a galaxy except instead of stars you are counting more complicated poker hands and betting strategies.

The best way to think of CFR+ (Counterfactual Regret Minimization Plus) is that you are playing a game of poker against yourself, but not just for fun – you are trying to be the best poker player possible. That is exactly what the CFR+ algorithm does. It has no idea how to play, and simply makes random moves. At the end of every game, it looks back at its decisions and thinks, “if I had done this instead of that, would I have done better?” and it will change its strategy by favouring better moves more often.

You could think about this, like learning how to ride a bike, but falling the first time and every time until you don’t fall anymore. Every time you fall off, you learn what not to do next time. CFR+ does this over billions of poker games, learning a strategy that minimizes its ” regret” which is the gap between a the move it made and what the best move would have been. The result is a strategy that nobody can beat, just as you eventually learn to stop falling off your bike and can start riding smoothly. By averaging over all of these games, CFR+ discovers a so-called Nash equilibrium in the sense that it constructs a smart enough strategy to never lose over the long run with any adversaries, including the best of the best.

I am especially fascinated by the fact that this strategy supports some long-accepted truisms about poker while rejecting others. For example, it can almost never “limp” (call the first bet) and any respectable player would acknowledge this with a simple nod of their head. It shows that sometimes you can have a better chance at being capped with a pair of twos (by raising the final bet) instead of a pair of aces. I can picture an experienced poker player reading this from home and saying “No Way!” while right at the same time they are reading it on the screen wondering if they are reading this correctly.

This study has provided humans with a great deal more than just a solution; it facilitates decision making and strategies of human players. The study implications go well beyond poker. These types of algorithms have immense applicability in situations to inform uncertain decisions and strategies in many other large decision invoking fields including security and medical. I wonder who would have even guessed that tools developed late at night playing poker could eventually figure into airport security protocols.

Turing once justified his gaming algorithm work because, quite frankly, it was hard to see as anything other than a jolly good time. This study attains that spirit. Solving for poker was more than just a scientific possible; it has been an interesting intellectual project. If only we could all have jobs that comprised solely of playing games all day for the purposes of science.

Lastly, it is clear that humans have been playing poker for thousands of years, and we have barely scratched the surface of the interplay of decision strategies. And who knows. The next big break through will be a study on another board game, like monopoly, where we will end up figuring out the exact strategy to deploy, so that family game nights end without everyone flipping the board up at the same time in frustrated despair…..
611 Words

Miximax-based betting approach

I’m reminded of a wonderful paper (Davidson A – Opponent Modeling in Poker: Learning and Playing in a Hostile, Uncertain Environment) that I found years ago. At the time, I was involved in coding projects and each time I felt I learned something new, it was like an epiphany. Now I can recall some of the best bits, although the details are somewhat hazy.

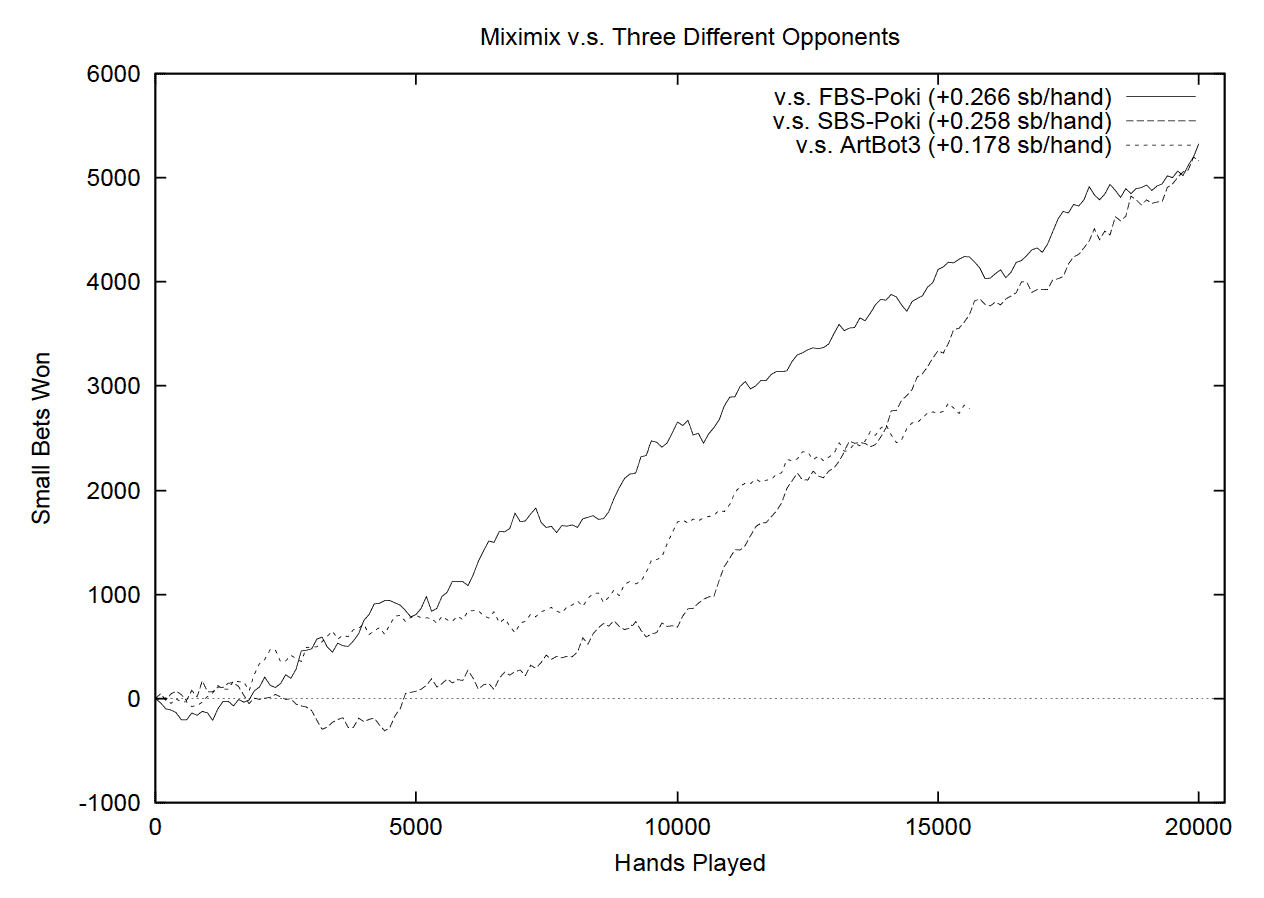
Davidson compared the Miximax-based betting strategy with three other programs, FBS-Poki, SBS-Poki, and ArtBot. ArtBot was a rather random player, most effectively passive. It was like playing with someone who is inconsistent almost out of a deliberate range of options. So, winning a hand against ArtBot helped, but the potential pots were small, so there aren’t any hundred thousand dollar pots. ArtBot did outperform FBS-Poki, who was a bit of a pushover, with about +0.35 small bets per hand won.

It is like having a range of different sparring partners to practice your moves with. Davidson was putting the Miximax player into play here, she began from nothing and had the ability to sometimes use a strategy developed during the previous games. This Miximax is not just a min-max player. It was a Miximix – a modified version, which does not always take the highest EV move. You can think of it as these are adding an element of randomness that is necessary so the Miximax player does not become predictable and limited to its choices and ensures it has open options when playing.

So, how did it go? Early on, Miximax struggles a little (as the simplistic new student might struggle with their first few games); but once Miximax understands the opponent-type, then it starts building up chips. Average over the FBS and SBS approach and Miximax is +0.4 small bets to +0.5 small bets per hand. ArtBot is struggling more, getting between +0.1 and +0.2 small bets every hand. The fast changing patterns of ArtBot seems to expose Miximax’s context trees flaws.

Then, Davidson adds a really interesting part which is only scratching the surface. The AI should the learn faster, either by developing further context trees or borrowing ideas from previous opponent models. The most frustrating is developing this into multiplayer games where the game tree is immense. Davidson hints that this may be too challenging to handle with more players unless they make shrink the game tree in a major way. This was difficult when desktop PCs could only run at 1GHz, and 4GB RAM was a lot of processing capacity. But now, not an issue.

I also remember that Davidson has this incredible finish where he quotes Josh Billings. Billings said “Life consists not in holding good cards, but in playing well those you hold”. In poker as in life, making better choices with what you have often overruns pure luck.

Miximax

There’s this figure which illustrates Miximax’s performance versus different opponents. It is really clear that as the AI learns more about its opponents it adjusts and drives up its win rate. Of course it might be erratic at first, but then it settles down once it begins accumulating data, just like the way that we humans all learn by our experiences.

So ultimately Davidson’s work illustrates that building a poker AI is more than just playing the numbers game. Its about operating through a shroud of uncertainty, and generating reasonable estimates based on patterns and probabilities. If poker and AI interest you, or just watching machines operate within games, this is a great read.

579 Words

Poker AI for Texas Hold’em

I’ve looked over some of the past work on poker AI, but after a long day of work and a few beers, I might be a little slow this evening. Nevertheless, I have had some time to read this paper on AI for Texas Hold’em, and I started to think about how we could make machines learn to bluff better than the average person.

To start, poker is more than a card game. Poker is an enigmatic fusion of statistics, psychology, and a dash of magic. Have you ever tried to guess if the guy sitting opposite of you is going to raise or fold? That is comparable to guess what my cat wants for dinner: impossible. So after the dust of chaos has settled, you look to artificial intelligence to help manage the storm.

Building a poker AI is like trying to teach chess to an infant, but with fewer snacks and slightly less chaos (most of the time). You will start with the basics: you first want to teach it to identify strong hands. Of course, there is a charm to poker because it has an element of randomness — you do not get to see the hands of your opponents. You want the AI to have to deal with partial information, to learn to make intelligent predictions, and to not think too poorly of itself when someone puts the hammer down.

For example, you are dealt the hand A♣ Q♥. The flop shows 3♦ 4♠ J♥. So, your AI has to determine, “What are the odds that this hand is any good?” It’s a bit like deciding if the leftover pizza you have in the fridge is still safe to eat a week later. Spoiler: it probably isn’t and your AI has a ~58.5% chance of getting it right. However, the more players involved, the odds decrease like your WiFi does during a critical Zoom call. Your shiny A-Q does not win only ~6.9% of the time against 5 opponents. Ouch.

Then we come to “potential” – as in, your hand is not great, but if you get lucky, could potentially give you a royal flush. It’s like gambling on your startup’s future success with 0% chance of prevailing. Take for example holding 6♦ 7♦ with a flop of 5♦ A♠ 8♦. Not looking good? If you hit the perfect turn and river, you may get a straight flush instead. So now your AI must go from “I’m screwed” to “maybe there’s a chance I will win!”

Before we move on, let’s talk about your opponents, because this is not solitaire! Your AI also has to model opponents in order to infer whether they are tight or loose, aggressive or passive. It’s like trying to figure out if your neighbor will give you your lawnmower back on time. Your AI uses neural networks, Bayes, possibly even something called particle filtering (whatever that is). I guess it’s like waving a magic wand over your opponent to try to guess their next move.

To increase the awe factor even more, your AI creates game trees for every possible outcome.It’s sort of like trying to think through, simultaneously, every possible conversation with your employer – it is helpful but tedious. And these trees help your AI reflect on the best course of action based on that value of every action. Raise, fold, call – all plotted out.

And now the goal is for AI to get smarter and better. Over millions of hands, it learns and becomes a poker master. Isn’t it somewhat similar to your child suddenly improving their score at a video game after 6 hours of virtual practice? Or like, your cat finally perfected the skill of knocking things off the table.

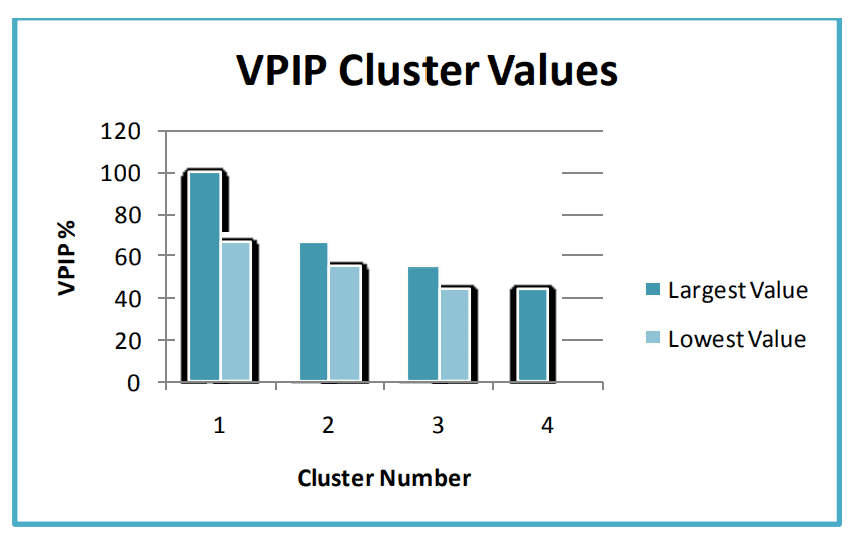
Look at this figure. The chart shows VPIP (Voluntarily Put Money In Pot) values for each player cluster. It is a clever way of saying, “Who’s the sucker who always bets?” It turns out – the lower the stakes, the more players want to see a flop – as if every cat has a dream of hitting that miracle river card.

In sum, developing a poker bot is not an easy task. You might think of it more like running a marathon, with some fresh math problem you’re handed at each mile. But that’s just so cool to see it outsmart humans or execute those clever moves? Priceless… Just make sure you provide your AI with decent data (we have billions of these hm2 files), somewhat like you would a cat – don’t give it too much at once, and don’t give it anything dangerous it can lash back at you!

And just a quick reminder, I’m open to collaborations and interesting projects. You can reach out to me on Linkedin, preferably starting right from the point. I have been involved in many projects, judging a poker AI competition, and developing the architecture of one of the best commercial poker AIs (my humble opinion) for my clients and some private projects. Ciao!

826 Words